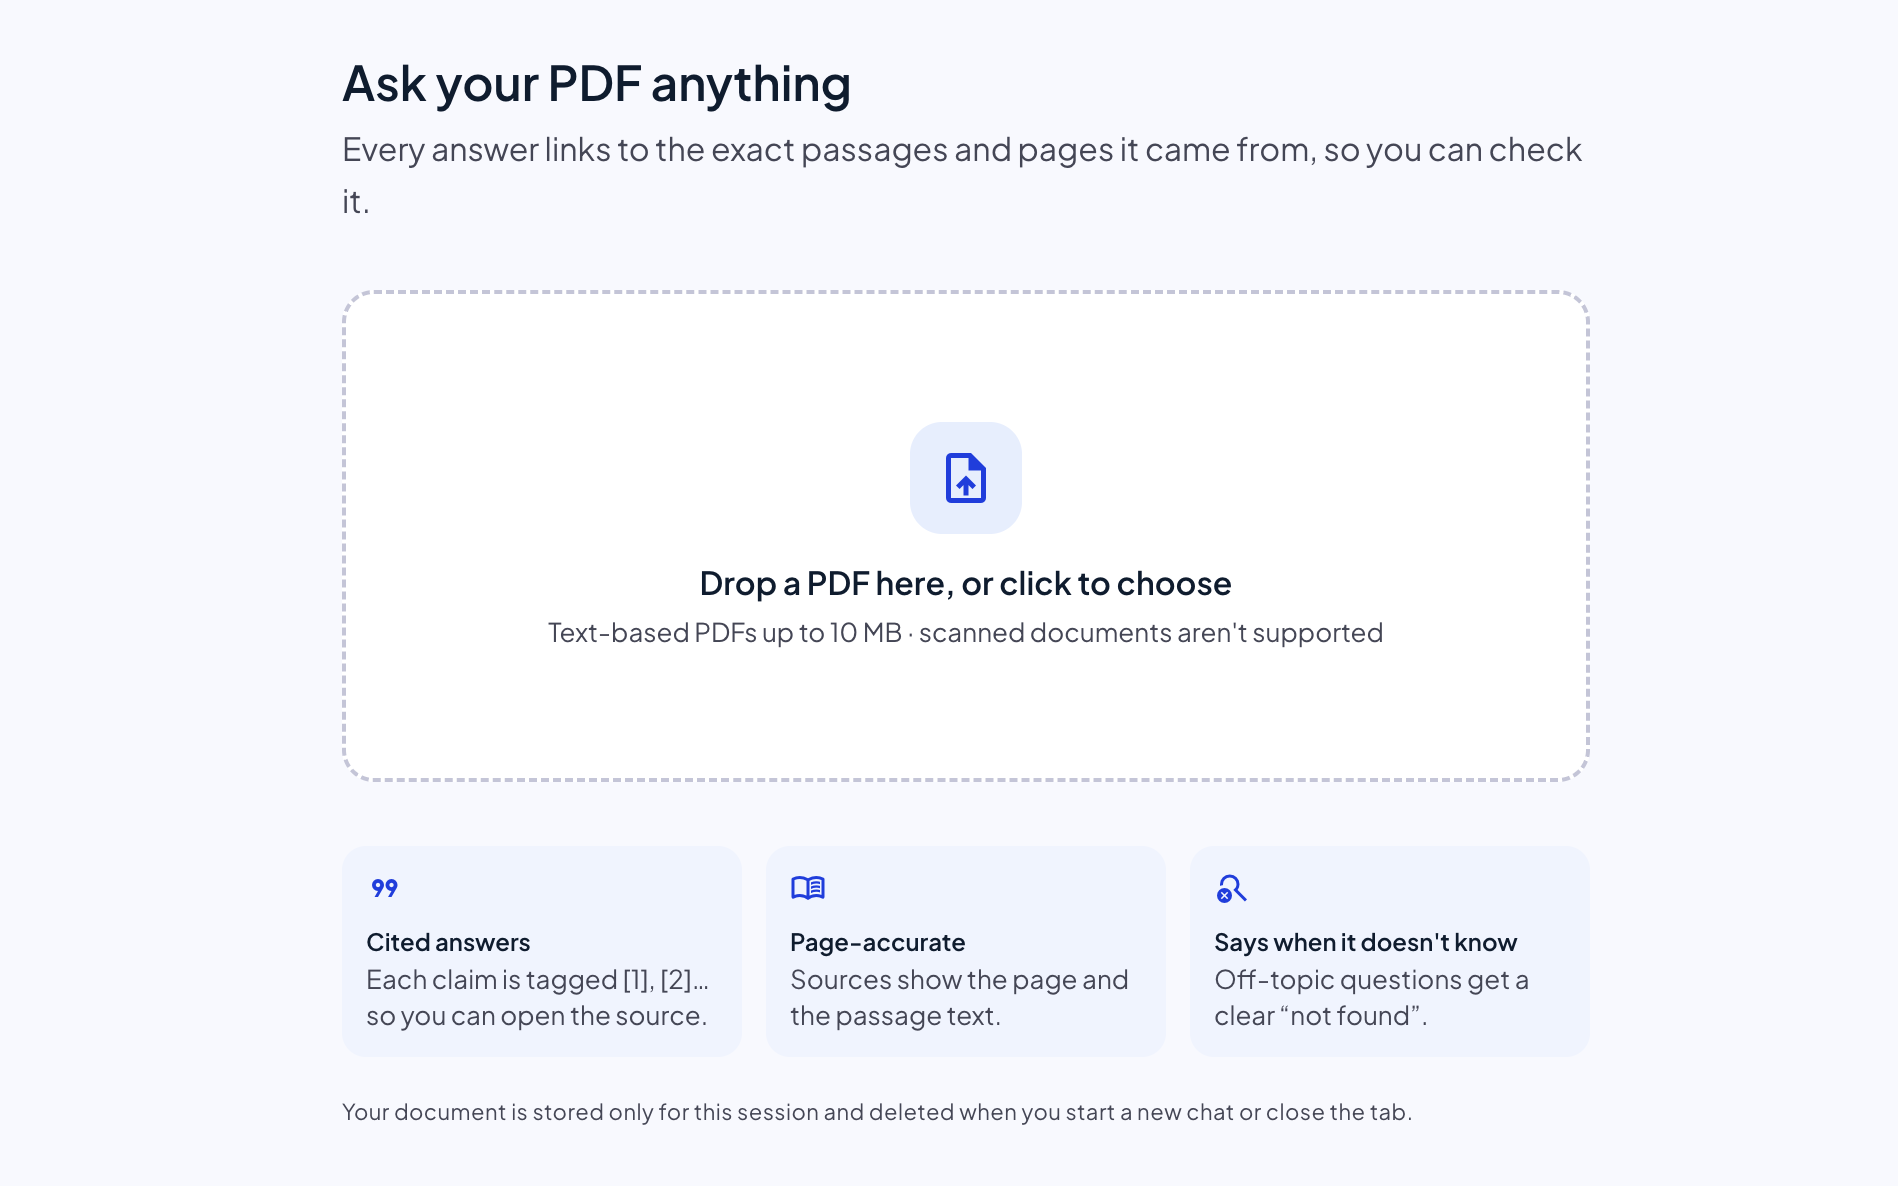
DocFlow is a document Q&A bot: you upload a PDF, ask questions in plain English, and every answer links to the exact paragraph and page it came from. I built it end to end with FastAPI, Supabase pgvector, Google Gemini and Next.js, then deployed it on free tiers. This post covers how it works, the problems I had to solve, and what I'd tell anyone building their first retrieval-augmented generation (RAG) app.
TL;DR
- What it does: answers questions about an uploaded PDF and shows the source passages, with page numbers and similarity scores, next to every answer.
- How it works: split the PDF into ~500-token chunks, embed them with Gemini, store them in Postgres with pgvector, retrieve the top 5 by cosine similarity, and have Gemini answer using only those passages.
- Key result: on a 22-question evaluation set, the right page ranked first for 100% of answerable questions, and 22 of 22 final answers were correct, including six correct refusals.
- Biggest lesson: a similarity threshold alone can't tell "relevant" from "about the same topic." You need a second safety net in the prompt, and you should choose the threshold with data, not intuition.
Try the live demo · Read the code
What is retrieval-augmented generation?
Retrieval-augmented generation (RAG) means the model answers from text you retrieve for it, not from memory. Instead of asking an LLM "what does my handbook say about leave?", you first find the handbook paragraphs about leave and hand them to the model with the question. The answer stays grounded in your document, and you can show the user exactly which paragraphs were used.
How DocFlow works
There are two flows.
Uploading a document (once per PDF):
- Parse the PDF with PyMuPDF, keeping page numbers and paragraph breaks.
- Chunk each page into overlapping pieces of about 500 tokens, splitting on paragraphs first, then lines, then sentences.
- Embed each chunk with Gemini's embedding model in batches of 100.
- Store the chunks and their 768-number vectors in Supabase Postgres with an HNSW index.
Asking a question (every time):
- Embed the question.
- Find the 5 most similar chunks with a cosine-similarity SQL function.
- If even the best match is weak, reply "I couldn't find that in the document" without calling the LLM.
- Otherwise, build a prompt with numbered sources
[1]–[5]and ask Gemini Flash to answer using only those, citing each claim. - Return the answer together with the source chunks, so the UI can turn
[1]into a clickable link to the passage.
Problems I solved (and what each one taught me)
1. Making citations trustworthy
A citation is only useful if it points somewhere exact. I chunk each page separately, so every chunk belongs to exactly one page and the source card can say "page 4" with confidence. The cost is that a paragraph spanning two pages gets split, which was an easy trade for accurate page numbers.
In the prompt, sources are numbered and the model must cite every claim as [n]. The backend then checks which numbers actually appear in the answer and drops any it invented, such as [9] when only five sources exist. The UI highlights cited sources and dims the ones that were retrieved but not used.
Lesson: design citations into the data model from day one. Adding page numbers later means re-ingesting everything.
2. Teaching the bot to say "I don't know"
Vector search always returns something. Ask "What is the capital of France?" about an employee handbook and you still get five chunks back, just with lower scores. So I added a score gate: if the best match is below a cutoff, skip the LLM and say the answer isn't in the document.
My first cutoff, 0.5, was a guess, and a live test immediately showed it was wrong: the France question scored 0.52 and slipped through. The model still refused, but only because of the prompt rule.
3. Choosing the cutoff with an eval set, not a guess
I built a small evaluation harness: a fictional six-page handbook (fictional so the model can't answer from its own knowledge), 16 answerable questions deliberately worded differently from the text ("vacation days" vs "paid annual leave"), and 6 off-topic questions. The script measures hit rate, mean reciprocal rank (MRR), and what share of questions each possible cutoff lets through.
| Metric | Result |
|---|---|
| Right page ranked first (hit rate @1) | 100% |
| Right page in the top 5 | 100% |
| Mean reciprocal rank | 1.000 |
| Correct final answers | 22 / 22 |
| Off-topic questions blocked by the gate alone (cutoff 0.56) | 83% |
The most useful finding was the one question the gate couldn't stop: "What is Northwind's current stock price?" scored 0.668, higher than the weakest real question at 0.610. A question about the document's subject that the document can't answer looks relevant to vector search. No single threshold separates those cases, so the system needs two layers: the gate cheaply blocks most off-topic questions, and a prompt rule ("if the sources don't contain the answer, reply with exactly this sentence") catches the rest.
Lesson: evaluate retrieval separately from generation, and keep the eval script in the repo so you can re-run it whenever you change models or chunk sizes.
4. Small infrastructure details that cost hours
- Embedding size: pgvector's HNSW index supports up to 2,000 dimensions, so Gemini's full 3,072-dimension vectors can't be indexed. Requesting 768 dimensions keeps search fast. Because Gemini only pre-normalizes full-size vectors, I normalize the 768-dimension ones myself.
- Vector format: sending a Python list through Supabase's REST API arrives as a Postgres array, which pgvector rejects. Formatting vectors as the text
[0.1,0.2,…]fixed it, and a unit test now guards it. - Partial writes: I embed every chunk before writing anything, so a Gemini failure leaves the database untouched. If an insert fails halfway, the half-written document is deleted, so it can't quietly degrade later answers.
- Model overloads: Gemini sometimes returns 503 "overloaded." The generator retries with exponential backoff (1, 2, 4, 8 seconds) and then falls back to a lighter model, while non-retryable errors like a bad request fail immediately so configuration mistakes stay visible.
5. Keeping privacy claims honest
My original UI mockup said documents lived "strictly in browser RAM" with "zero server retention." That wasn't true: chunks and embeddings live in Postgres while you chat. Rather than ship a false claim, I made a true one: the document is deleted when you start a new chat, replace the file, or close the tab. Closing the tab sends a navigator.sendBeacon request, and an hourly pg_cron job removes anything older than two hours in case a browser crashes before it can clean up.
Lesson: read your UI copy as a promise. If the backend can't keep it, change the backend or change the copy.
6. A React bug that only appeared in a new browser
The chat crashed with destroy is not a function. The cause was a one-line effect, useEffect(() => el.scrollIntoView(), []). An arrow function without braces returns its value, and React treats whatever an effect returns as a cleanup function. Newer browsers make scrollIntoView() return a Promise, so React tried to call a Promise. Adding braces fixed it, and the type checker never complained. That's a good argument for testing the app by hand in a current browser, not just running unit tests.
7. Production on free tiers
DocFlow runs on Vercel (frontend), Render (FastAPI in Docker) and Supabase (Postgres). Free tiers come with conditions, and each one needed a fix:
- Cold starts: Render's free plan sleeps after 15 idle minutes and takes about a minute to wake. The upload screen checks the server on load and shows "Waking up the server…" instead of looking broken.
- Database pausing: Supabase pauses free projects after about a week of inactivity. A GitHub Actions job calls a
/readyendpoint, which runs a tiny query, every three days. - Quota abuse: a public URL means anyone can use your Gemini key. Per-IP rate limits (10 uploads and 60 questions per hour) return a friendly 429 instead of draining the quota.
How I tested it
The backend depends on three small interfaces: an embedder, a vector store and a generator. Tests swap in fakes, such as an in-memory store and a word-hashing embedder, so 84 backend tests run offline in about a second. 8 live tests hit the real Gemini and Supabase APIs, and 26 frontend tests cover the citation parser, the API client's error messages and the chat state. CI runs everything and a production build on every push.
What I'd build next
- Hybrid search: combine vector search with Postgres full-text search, so exact terms like product codes are never missed.
- Reranking: retrieve 20 candidates, then rerank to the best 5.
- Streaming answers: show words as they're generated.
- Follow-up questions: rewrite "what about for contractors?" into a standalone question before searching.
FAQ
How does a RAG app avoid hallucinations? It retrieves passages from your document, tells the model to answer only from them, and refuses when nothing relevant is found. DocFlow uses two refusal layers: a similarity cutoff before the LLM call, and a prompt rule the model must follow when the passages don't contain the answer.
Why use pgvector instead of a dedicated vector database? For one app with modest data, keeping vectors next to the rest of your data in Postgres is simpler: one database, plain SQL, and row-level security. pgvector's HNSW index keeps similarity search fast.
What chunk size should I use for RAG? About 500 tokens with a small overlap is a solid starting point. More important than the exact number is splitting on natural boundaries (paragraphs, then sentences) and measuring the result with an eval set.
How do you choose a similarity threshold? Run a labelled set of answerable and off-topic questions, sweep the cutoff, and pick the value that keeps all real questions while blocking the most off-topic ones. For DocFlow that was 0.56. Re-run it whenever you change the embedding model.
How much does it cost to run? DocFlow runs entirely on free tiers: Vercel Hobby, Render's free web service, Supabase's free plan and the Gemini API free tier. The trade-off is a cold start of about a minute after the server has been idle.
The full source, including the eval harness and deployment files, is on GitHub. You can try DocFlow here.
Related build: Open the live project ↗